
Whisper
OpenAI's speech-to-text model
Episodes
-
 #6473: Why Whispering Breaks Speech Recognition PhysicsWhispering completely removes fundamental frequency and pitch, forcing speech recognition models to rely on subtle duration cues.
-
 #6469: Why Switching Off One Attention Head Changes EverythingMasking just three decoder heads in Whisper drops hallucination on silent audio clips from 99.97% down to 24.1%.
-
 #6464: Teaching Speech Recognizers to Stay QuietMasking just three self-attention heads in Whisper large-v3 cuts hallucinations on non-speech audio by over eighty percent.
-
 #6463: Why Training Speech Recognition From Scratch FailsThirty-two hours of speech provides just three hundred thousand words of text, making from-scratch speech models struggle with basic spelling.
-
 #6453: Who Actually Won the Open Weight RaceWith over four billion downloads, the most downloaded open-weight model in history is an embedding tool, not a chatbot.
-
 #6448: Why Fast Model Microtraining Needs an Evaluation GateA speech model fine-tuning run can cost twenty-three cents in twenty minutes, but unmonitored updates silently erase older vocabulary.
-
 #6444: Teaching Speech Models to Collapse Spelled WordsFine-tuning formatting rules takes surprisingly little data: a Johns Hopkins study found truecasing accuracy jumps with only fifty documents.
-
 #6423: How Spoken Safety Rules Became Machine Training DataA 1994 Eurocontrol study showed early speech recognition parsing controller commands correctly eighty-one percent of the time in simulator trials.
-
 #6419: Why Bluetooth Headsets Still Sound Like AM RadioTurning on a Bluetooth headset microphone drops the connection to narrowband audio as low as 8 kHz, even when using a bundled USB dongle.
-
 #6409: Why Speech Models Break at Chunk SeamsShifting an audio transcription window by just one second can lose entire words or drop capitals mid-sentence without changing the model weights.
-
 #6366: Why Training Recipes Matter More Than Model SizeAltering learning-rate timing alone improved global word error rates by twelve absolute percentage points in speech recognition experiments.
-
 #6365: Teaching Speech Models to Transcribe Bilingual SlangFine-tuning Parakeet with 77 minutes of speech cut Hebrew-English code-switching errors nearly in half, but later gains required far more audio.
-
 #6344: Training Text Models to Know When Not to EditIn a 2023 WMT Marathi task, an LLM post-editor modified over 90% of sentences but improved only around 20%.
-
 #6332: Why Extra Voice Hours Settle Bilingual SpeechFine-tuning Parakeet TDT on fifteen hours of bilingual speech cut error rates from 13.7% to 4.9% by resolving contextual variation.
-
 #6302: Why Fine-Tuning Whisper Won't Stop Duplicated TextWhisper evaluates transcripts against a gzip compression threshold of 2.4, rejecting repetitive text before retrying at higher temperatures.
-
 #6298: Why Dictation Models Steal Other People's VoicesStock speech models lack target-speaker conditioning, defaulting to transcribing whichever competing voice is loudest or most predictable.
-
 #6297: Teaching Dictation Models to Ignore Other VoicesEvaluating Whisper on non-speech clips revealed entire invented phrases in roughly one percent of transcriptions.
-
 #6296: Why Speech Recognizers Cut Off Hesitant SpeakersBetween speakers, conversational handover averages 200 milliseconds, but planning pauses inside a turn naturally take seconds.
-
 #6244: When Your Fine-Tune Isn't Done Learning YetFalling loss, 90% word error rate, and a model that still says "Derry gym lag." What undertraining actually looks like — and when more epochs won't...
-
 #6223: How Many Epochs Does Fine-Tuning Actually Need?Epochs are a receipt, not a plan. How to pick a training ceiling, read the curves, and know when to stop.
-
 #6196: Fine-Tuning ASR: When Your Model Memorizes YouYour fine-tuned speech model aces your training recordings — but does it actually work on fresh audio?
-
 #6192: What Actually Happens When You Train a ModelData in, model out — except the "data" is pairs, the split is the whole game, and one leaked speaker can fake your score.
-
 #6191: What Actually Happens During Fine-TuningSixteen bytes per parameter in, two out — a walk through the forward pass, backward pass, and optimizer that turn a dataset into new weights.
-
 #6180: Mapping Code-Switching: 113 Pairs, No CommunityResearchers count 113 code-switched language pairs — but a pair is just a label on a file, not a community of speakers.
-
 #6161: Turning Words Into Sound: G2P, IPA, and the Hebrew Vowel ProblemText-to-phonetics tools exist, but the neural ones guess wrong on exactly the words you care about — names, brands, and Hebrew.
-
 #6159: When a Speech Model Can't Decide How to Write DollarsOne dataset says "$20," another says "twenty dollars." Fine-tuning a speech model means finding out which convention wins — and why it matters.
-
 #6158: Naming the ASR Sub-Tasks Nobody MappedA 2001 linguistics paper already named Daniel's problem — but it points the other way. So what do you call a fine-tune set that expands "F Y I" to ...
-
 #6114: We Reviewed Our Own Worst EpisodeTwo AI hosts listen back to episode fifteen and critique the voices, the writing, and the mistakes they can't unhear.
-
 #6055: How to Fine-Tune ASR on Noisy AudioA small noise library mixed into clean speech beats collecting hours of noisy recordings. Here's the ratio that actually works.
-
 #6047: A Human Guest on His Own AI PodcastDaniel built an AI podcast with cloned voices — then sat down as a guest on it. What six thousand episodes taught him about prompts.
-
 #6028: ASR vs Multimodal LLMs: What Actually WonDedicated ASR plus a cleanup model is quietly beating end-to-end dictation on the hardware you already own.
-
 #6027: Can You Snap Two Fine-Tunes Together Like LEGO?Two fine-tunes, one base model, and a question from Jerusalem: can you merge Hebrew code-switching with technical vocab — without retraining?
-
 #6023: How Much Voice Data Is Enough?Two hours of phone recordings took Hebrew code-switching from 20% to 60%. But when does more data stop mattering?
-
 #6022: Fine-Tuning for Code-Switched Hebrew on 2 Hours of AudioTwo hours of one man's voice beat models trained on 120,000 hours — but only for code-switched Hebrew.
-
 #5975: Merging vs Distillation: Can Two Models Become One?Merging and distillation get lumped together, but they're opposites. One composes existing capability; the other has to teach it.
-
 #5974: One Model or Two? ASR Cleanup ExplainedIf speech models can punctuate and capitalize on their own, why does a separate 484MB cleanup model exist at all?
-
 #5962: How Word Error Rate Lies to UsWER is the number everyone reports for speech recognition — and the one that agrees with human judgment least. Here's what it actually measures.
-
 #5941: Five Minutes Reading Your Dictation PromptA listener's speech-to-text cleanup prompt, read out in full — then stress-tested against what ASR actually gets wrong.
-
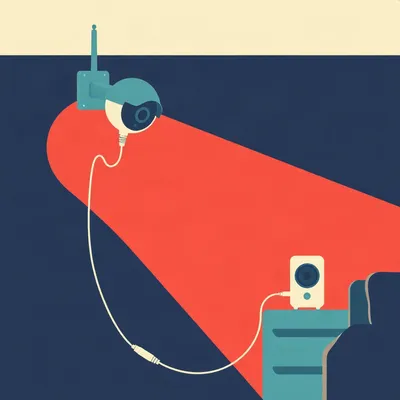 #5918: Splitting One Camera's Audio for a Baby MonitorOne IP camera, two jobs: an open audio line for the nursery and Frigate's cry detection. Here's how go2rtc and Icecast fit together.
-
 #5868: Fine-Tuning Parakeet for Um-Free, Hebrish SpeechParakeet runs great on a phone — but fine-tuning it happens on a GPU. Here's the actual recipe for dropping ums and catching Hebrew.
-
 #5485: Fine-Tuning Parakeet for Hebrew and Your Own JargonNVIDIA's Parakeet beats Whisper on Android — but can you teach it Hebrew, or just your own jargon? Two answers, one much happier.
-
 #5482: When AI Edits Your Words: The Off Switch ProblemA tool that works reliably — and still gets switched off. What over-editing studies reveal about why AI rewrites more than you asked.
-
 #5464: Your Keyboard's Hidden Data ProblemYour keyboard knows your email address, your phrases, your habits — and you can't take any of it with you.
-
 #5460: Four Small Models, One Android Phone: Does It Actually Work?A chained on-device dictation pipeline — VAD, ASR, cleanup — and why "it feels smooth" isn't the same as knowing it works.
-
 #5456: Parakeet vs Whisper: Picking a Phone ASR ModelWhy Whisper loses on Android, why Parakeet v2 beat v3, and how to benchmark speech-to-text without any tooling.
-
 #5430: Two Boxes: ASR and the Text Fixer Behind ItPunctuation, casing, ITN, disfluency — the four-job layer between raw ASR output and text you can actually read.
-
 #5422: Switching Android Keyboards Without the Tap DanceOne listener wants a one-tap jump between his Parakeet voice keyboard and his typing keyboard. Android says no — unless you know the trick.
-
 #5419: The Attention Budget in Your PocketWhy phone dictation runs out of room, and how bounded attention windows buy you punctuation without blowing your memory budget.
-
 #5390: Chaining Small Models for Dictation CleanupDaniel's Android dictation fork won't render "three point five" as a decimal. How many models does cleanup actually need?
-
 #5388: Android's Split Keyboard and Voice Input ProblemAndroid separates keyboards from speech engines by design. Most apps weld them back together.
-
 #5384: Android ASR Runtimes: LiteRT, ExecuTorch, and Why Your Phone Has No VRAMWhy does your phone have no VRAM number? A tour of Android's runtime layer and what it takes to run ASR locally.
-
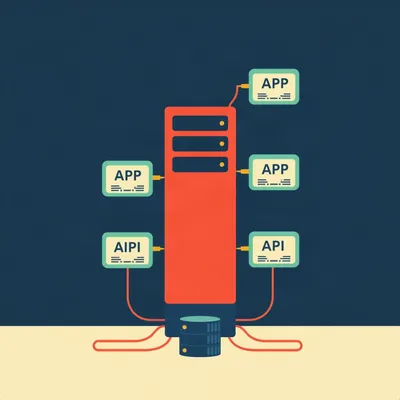 #4973: Building a Pure AI Inference ServerWhy your "AI server" should look more like a database than a web app, and how to actually build one.
-
 #4958: Multi-Model Transcription with LLM ReconciliationUsing multiple transcription engines and an LLM judge to catch errors in voice-to-text — especially tricky technical terms.
-
 #4920: Local Dictation on Android: The Real BottlenecksWhy on-device speech-to-text on Android hits a wall at 30 seconds — and what silicon actually matters.
-
 #4919: Parakeet vs Whisper: On-Device Dictation ShowdownNVIDIA Parakeet beats Whisper on phone dictation despite having more parameters. Here's why architecture matters more than model size.
-
 #4667: How Transformers Killed the Robot VoiceFrom espeak's robotic squawk to neural voices with added "ums" — how transformers made speech synthesis human.
-
 #4376: Which Mic Actually Lowers Word Error Rate?Laptop mics hit 18% WER. A $70 mic drops it to 4%. Here's what actually works for voice-first dictation.
-
 #4312: Why Speech-to-Text Still Fails at Its Own NameWhen OpenAI's Whisper misheard its own name as "Wispr," it revealed why 95% word accuracy still isn't good enough.
-
 #4274: Fixing Loop-Damaged Podcasts with AI and FFmpegCan an AI agent detect repeated audio, generate FFmpeg commands, and overwrite files in cloud storage without breaking RSS?
-
 #2982: Why Your TTS Model Nails "Shabbat" but Not "Keren HishtalmutWhy multilingual TTS models handle loanwords but fail at niche vocabulary — and what you can do about it.
-
 #2754: Why Your Dictation Setup Might Be WrongModern ASR is shockingly robust. The biggest predictor of accuracy? How well your audio matches its training data.
-
 #2643: How Stenographers Type 300 Words Per MinuteCourt reporters don’t type letters—they chord syllables at 300 words per minute. Here’s how it works and why AI can’t replace them yet.
-
 #2604: Self-Hosted Screen Recording: Tools Beyond LoomPractical tools and trade-offs for async video documentation with real data control across platforms including Linux.
-
 #2597: Voice Control for Renters: $25 Per Room, No Wall DamageDistributed voice control on a budget with wake words, centralized processing, and zero wall damage — perfect for rentals.
-
 #2590: The Uncanny Valley of Clean SpeechHow transformer models distinguish "um" from meaningful speech — and why removing too much makes you sound like a robot.
-
 #2585: The Pristine Key Namespace Nobody UsesHow unused keyboard keys, custom firmware, and layered macros can transform your workflow.
-
 #2582: What Your Browser Does to Mic Audio Before It Reaches Your ServergetUserMedia returns audio, but not raw audio. Here's what browsers actually do to your mic feed before it hits your server.
-
 #2479: The Screaming Baby Stress TestChoosing the right headset and control method for dictation when you're holding a baby who won't stop screaming.
-
 #2272: The AI Transcription Sweet SpotDoes higher-quality audio make AI transcription worse? New research reveals a surprising "sweet spot" for bitrate, challenging a core assumption of...
-
 #1778: Audio Is the New "Read Later" GraveyardWhy listening to AI conversations beats reading dense PDFs, and how serverless GPUs make it cheap.
-
 #1724: When AI Dubbing Swaps Your GenderHow does YouTube translate a video with one click? We explore the tech behind auto-dubbing, from sandwich models to voice cloning.
-
 #1555: Beyond Whisper: NVIDIA’s Real-Time Speech RevolutionMove over Whisper. NVIDIA's new models offer 10x speed increases and better accuracy for real-time speech-to-text.
-
 #1539: Escaping the Cloud Dictation TrapStop shouting at your phone. Discover how dedicated hardware and local AI are making instant, private voice-to-text a reality.
-
 #1218: The Architectural Divide Between Batch and Live SpeechWhy does voice typing feel so clunky compared to recording a memo? We explore the technical hurdles of real-time AI transcription.
-
 #1216: AI Wearables: Local Sovereignty vs. The Subscription TrapDiscover the trade-offs between sleek AI subscriptions and open-source sovereignty. Can local processing save your data from the cloud?
-
 #1079: When Thin Walls Betray Your VoiceHow do you keep your voice private when walls are thin? Explore the high-tech muzzles and throat mics designed for the remote work era.
-
 #832: How AI Rebuilt the Curb CutFrom Whisper to smart prosthetics, discover how AI is transforming accessibility and granting independence to millions.
-
 #682: Why Your Phone Mic Beats Your Studio HeadsetWhy does a phone mic outperform a pro headset for AI transcription? Herman and Corn dive into the physics of MEMS and the truth about audio quality.
-
 #332: Who’s Talking? The Tech of Speaker IdentificationHerman and Corn break down the difference between speaker diarization and identification to help automate meeting transcripts.
-
 #196: Why Your Irish Accent Sounds AmericanHerman and Corn dive into the mechanics of neural text-to-speech, exploring how AI masters human prosody and the "average voice" accent problem.
-
 #91: The Story Behind the ShowDaniel Rosehill explains the origins, motivation, and technical pipeline behind the My Weird Prompts AI-generated podcast.
-
 #57: From Lawyers in Limousines to Developers in Their PJs: The Voice Tech RevolutionFrom limo-riding lawyers to pajama-clad coders, voice tech is booming. Discover how AI is making it a force for good.
-
 #54: How AI Unifies Images, Audio, and TextOmnimodal AI: How do models process images, audio, video, and text all at once? Discover the engineering behind AI that accepts anything.
-
 #48: Renting vs. Building: The Hidden Choices in AI InferenceEver wonder how AI magic happens? We demystify AI inference, exploring where and how models truly operate.
-
 #29: Will Multimodal Audio Replace Speech-to-Text?Is multimodal audio the future? We explore if AI can truly displace traditional speech-to-text for a screen-free world.
-
 #28: Your AI, Evolving: Beyond the Static SnapshotIs your AI an "old suit" that no longer fits? We explore evolving AI that learns and adapts with you.
-
 #26: Fine-Tuning AI to Understand Your VoiceVoice typing is changing everything. Join us as we explore the revolution of personalizing Whisper!
-
 #15: AI Gets Personal: The Power of Voice Fine-TuningAI that understands *your* voice? Dive into the fascinating world of fine-tuning and discover how AI gets personal.
-
 #9: Benchmarking Custom ASR Tools - Beyond The WERBenchmarking custom ASR fine-tunes: We're diving deep beyond the WER to truly measure performance.
-
 #6: How To Fine Tune WhisperBuild your own AI transcription tool! We'll walk you through fine-tuning Whisper, from data to notebook.
-
 #7: Building Custom ASR ToolsEver wondered how to build your own ASR tools from scratch? Discover the why and how in this episode!
-
 #4: If Your Voice Ages, Does Your Fine-Tune Become Useless?Your voice changes, but your fine-tuned model shouldn't become useless. We explore the biology of the larynx and ASR.
-
 #8: Building Your Own WhisperEver wondered if you could build your own speech recognition tool? We dive deep into crafting custom ASR.
-
 #2: Local STT For AMD GPU OwnersAMD GPU? No problem! Dive into local AI adventures like on-device speech to text.
-
 #11: How Does Fine Tuning Work Anyway?Unlock the secrets of AI fine-tuning. Discover how your small dataset can shape a giant model.
-
 #10: How ASR Went From Frustration To ... Whisper MagicSpeech to text: from frustrating to fantastic. Uncover the magic behind its rapid rise and connection to the AI boom!
-
 #5: Fine-Tuning ASR For Maximal UsabilityFine-tuned ASR is just the start. Discover the next steps for deployment and maximizing usability.