
Databases
78 episodes · Page 2 of 4
#3673: Knowledge Graphs vs SQL: How Custom Relationships Change Retrieval
Why naming relationships (not just connecting data) transforms how you retrieve information.
#3667: When Your Podcast Outgrows Its Feed
3,700 episodes. 68 days of audio. One RSS feed designed for 10 blog posts. Can podcast infrastructure handle this?
#2829: The Missing CRUD Framework for Real Code
What actually gives you a real starting point for internal tools — not a platform, not a service, but code you own and deploy.
#2676: Vector Database Schema Design for AI Memory Layers
Stop dumping vectors blindly. Design metadata schemas and namespaces for retrieval that actually works at scale.
#2673: The Embedding Coupling Problem: Editing Vector Stores
Can you edit or delete individual chunks in Pinecone? And can you actually back up a vector index? Yes—but with critical caveats.
#2550: Idempotent Pipelines: Checkpoints, Manifests & Safe Re-Runs
How to design scripts and pipelines so re-running them is safe, even after a crash mid-execution.
#2548: Static vs Server-Side: What Actually Happens When You Deploy
The moment you see content appear instantly on production and realize it wasn't pre-built — that's when architecture gets interesting.
#2506: Squashing Database Migrations Without Breaking Production
How to safely squash old migrations, cut deploy times, and generate schema documentation at version boundaries.
#2501: Describing a Neighborhood: Databases Without Screens
Can you design a relational database using only your voice? We coach a beginner through PostgreSQL from scratch.
#2476: Database Backups Without the Bloat
pg_dump, WAL archiving, and the free tools that beat expensive commercial backup software.
#2465: JSON-L vs Parquet: When Each Format Wins
How far can JSON-L scale before it breaks? And why does Parquet dominate for millions of rows?
#2459: Drizzle vs Prisma: Which ORM Wins for AI-Native Backends?
Comparing Drizzle and Prisma for AI-native backends, MCP servers, and the future of agent-centric development.
#2458: Can Graph Databases Go Mainstream?
Graph databases are powerful but niche. Will they ever power mainstream CRMs and ERPs?
#2452: When BIM Breaks the SQL Analogy
How BIM's cascading changes eliminate coordination errors — and where the SQL analogy breaks down.
#2444: Custom IDs: UUIDs vs Human-Readable Keys
How to design database IDs that balance security, human readability, and performance — with lessons from Stripe and TypeID.
#2440: Build Your Own CRM With AI Agents
Off-the-shelf CRMs are built for sales teams, not solo operators. Here's why building your own with AI might be smarter.
#2439: AI Collapses the Framework Decision
Why Airtable fails for multi-user tools, and how AI builders are changing the framework decision for small businesses.
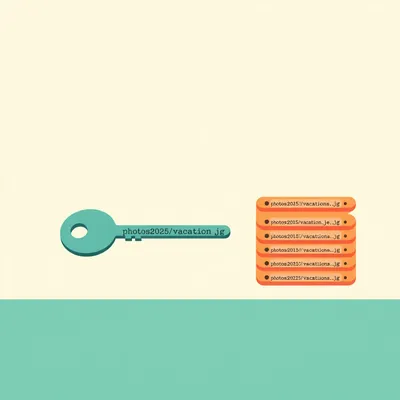
#2438: The Folder Illusion: How Object Storage Fakes Hierarchy
Blobs, flat namespaces, and why those "folders" in cloud storage are complete illusions.
#2436: The One-in-Ten-Thousand Design Constraint
How survey-grade precision and Python tools shape local map projections — and the silent failures that break your analysis.
#2435: The Hidden Difficulty of Data Modeling
Stop designing database schemas from scratch. Here's where to find ready-made templates for common business apps.
#2434: From Spreadsheets to Databases: The Mental Shift
Stop treating databases like bigger spreadsheets. Learn the one conceptual shift that actually matters.
#2401: Designing Data Models That Mirror Your Work
Why 60% of small businesses hate off-the-shelf SaaS—and how to build tools that actually fit your workflow.
#2346: Your Schema Is a Contract
How to design relational schemas that don’t haunt you later—entity modeling, normalization tradeoffs, and when (not) to use JSON columns.
#2271: Vector Search in a Single File
What if you could do vector search with just SQLite? We explore sqlite-vec, the extension that adds embeddings to the world's simplest database, an...