
Redis
In-memory data store for caching
Episodes
-
 #5870: Homebox Fork's Two Backend Scripts Need a Real Job RunnerA Homebox fork has two incremental scripts — WebP conversion and AI image enrichment — and no scheduler built to run them safely.
-
 #5812: One Number, Every Hard Question: Agent Session StateA shopping bot that holds one cart total turns out to contain every hard problem in agent state management.
-
 #4902: Backward Batching: Fixing Slow Uploads Without Blocking UsersHow one developer used background threads and deferred AI processing to fix a cataloguing workflow.
-
 #4546: Redis: What It Actually Is and Why It's EverywhereRedis powers half the internet's caching, but almost nobody knows what it actually is. We break it down from the ground up.
-
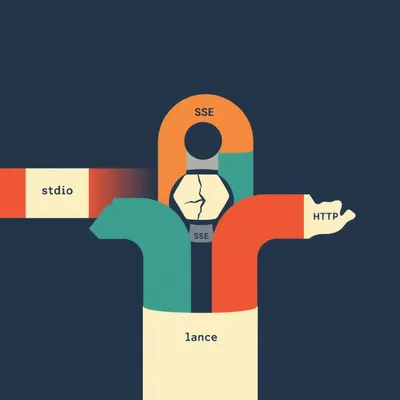 #4521: MCP Transport Architecture in 2026: Gateway DesignThree transports, one gateway. How to bridge stdio, legacy SSE, and streamable HTTP in production.
-
 #4445: AI Agents Keep Undoing Each Other's WorkWhy AI coding agents silently revert each other's fixes — and three memory strategies that prevent it.
-
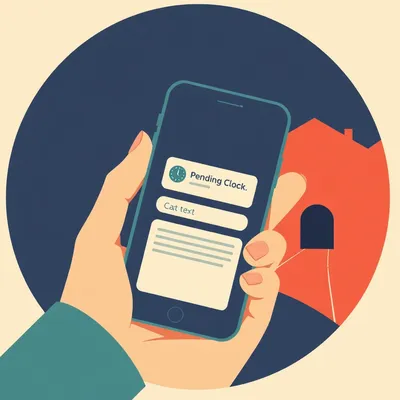 #4339: How Text Survives a Tunnel: Offline Queueing Deep DiveWhat happens when you tap send in a tunnel? The browser, service worker, and backend dance that makes tiny payloads survive offline.
-
 #4317: The Ladder of Minimal Linux SystemsFrom scratch containers to BusyBox to Alpine — how barebones can you go and still serve production traffic?
-
 #3793: Solving the Bulk Redirect Problem for System MigrationsWhat tools exist for managing bulk redirect mappings when QR codes are already stuck on physical assets?
-
 #2368: The Multi-Stage Pipeline Behind Netflix's RecommendationsUnpacking the multi-stage AI pipeline behind Netflix, Spotify, and Amazon’s "you might also like" suggestions—from candidate generation to real-tim...
-
 #2141: Choosing Your Durable Execution PlatformWhy building AI agents means managing infrastructure. We explore durable execution backends like Temporal and AWS Step Functions.
-
 #2139: AI Wargame Memory: Beyond the Context WindowWhy simply extending context windows fails in multi-agent simulations, and how layered memory architectures preserve strategic fidelity.
-
 #2113: Goldfish vs Elephant: The Stateful Agent DilemmaStateless agents are cheap and fast, but stateful ones remember your window seat. Which architecture wins?
-
 #1931: Where Your AI Pipeline Actually DiesWhy do AI pipelines crash? It’s not the models—it’s the plumbing. We break down how to manage data between stages.
-
 #1211: Escaping JOIN Hell: The SQL Developer’s Guide to Neo4jStop struggling with 15-deep JOINs. Learn how Neo4j turns relationships into first-class citizens for faster, more intuitive data modeling.
-
 #1124: The Database Explosion: Why One Size No Longer Fits AllFrom vector stores to edge computing, discover why the world now has over 1,000 databases and why Postgres isn't always the answer.
-
 #841: AI Gateways: Building Robust Infrastructure with LiteLLMDiscover how AI gateways like LiteLLM provide redundancy, caching, and unified tool access for scalable application development.
-
 #689: The Secret Life of Webhooks: How "Always On" Costs NothingEver wonder how webhooks stay "always on" without costing a fortune? Herman and Corn dive into the kernel magic of sockets and interrupts.
-
 #605: Why Your Home Lab Can't Be One Big ComputerHerman and Corn explore how to turn separate servers into a unified supercomputer using high-speed interlinks and resource pooling.