
llama.cpp
CPU inference engine with quantization support
Episodes
-
 #6191: What Actually Happens During Fine-TuningSixteen bytes per parameter in, two out — a walk through the forward pass, backward pass, and optimizer that turn a dataset into new weights.
-
 #5991: Batch Inference on Your Own GPU: vLLM, SGLang, Ollama, llama.cppHosted batch APIs sell you half-price tokens. Here's how to get the same file-in, file-out workflow on your own Linux box.
-
 #5969: Ubuntu 26.04 LTS: Is Staying on LTS Still a Trade-Off?Ubuntu 26.04 LTS shipped in April. Point releases, HWE kernels, and SRUs have quietly closed most of the freshness gap — but not everywhere.
-
 #5963: Running One Model Across Mismatched GPUsTensor, pipeline, or offload? What actually happens when you run one model across several GPUs — including mismatched ones.
-
 #5960: There's No Such Thing as Tokens Per SecondWhy one tokens-per-second number can't describe an LLM server — and which metrics actually tell you if it's working.
-
 #5900: Serving DeepSeek-V4.1-Flash on Your Own GPUFive inference engines, one frontier MoE, and a shortlist that collapses depending on which GPU you already bought.
-
 #5898: ROCm 10.1: AMD's Software Stack Finally Grows UpThree ROCm releases in six months — build system, agentic tooling, data movement. What actually changed for AMD GPU owners.
-
 #5853: Who Actually Competes With Hugging Face?2.96 million model repos, and 85.6% have under 200 downloads. What ModelScope, Kaggle, and Ollama actually do differently.
-
 #5673: Why Lowering Temperature Broke Daniel's ScriptsLowering temperature should make output safer, not incoherent. Daniel's DeepSeek scripts say otherwise — and the reason may be stranger than he thi...
-
 #5436: Small Models as Rewriters, Not WritersWhy "don't say X" prompts backfire, and how a tiny grammar-constrained model can scrub a script without breaking its grammar.
-
 #5393: Fine-Tuning a Model on 100 Hand-Edited AnswersYou don't need 10,000 examples to make a model sound like you. The real number is closer to 100 — if the edits are opinionated.
-
 #5384: Android ASR Runtimes: LiteRT, ExecuTorch, and Why Your Phone Has No VRAMWhy does your phone have no VRAM number? A tour of Android's runtime layer and what it takes to run ASR locally.
-
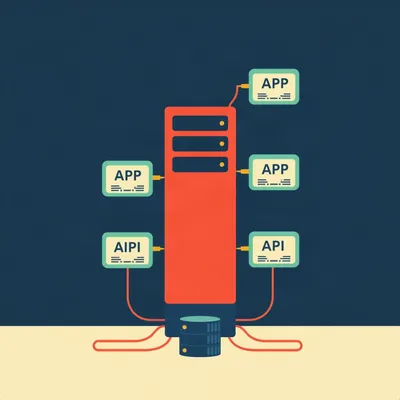 #4973: Building a Pure AI Inference ServerWhy your "AI server" should look more like a database than a web app, and how to actually build one.
-
 #4972: CPU vs GPU Inference: When to Skip the GPUWhy running AI on CPU isn't a toy — and when the GPU advantage vanishes.
-
 #4588: The Hidden Cost of Conversational AI: Why Stateless LLM Calls MatterWhy conversational AI tools are making batch document processing slower, costlier, and less reliable — and what to do about it.
-
 #2911: Building a $180 Privacy-First AI WearableHow Omi's $99 dev kit lets you build a local-first voice productivity system that watches your screen.
-
 #2693: When AI Ignores Your Style GuideWhy your AI ignores formatting instructions and how to fix it with pipeline architecture, not model swaps.
-
 #2171: How IQT Labs Built a Wargaming LLM (Then Archived It)A deep code review of Snowglobe, IQT Labs' open-source LLM wargaming system that ran real national security simulations before being archived. What...
-
 #2041: The "MPEG Moment" for AI: Llamafile & Native ModelsWhy are we squeezing massive cloud models onto desktops? Meet the "native" AI revolution.
-
 #2040: The Rebellion Against Big Tech's AI Lock-InWhy run LLMs locally? We break down Ollama, llama.cpp, vLLM, and llamafile—and when to use each.
-
 #2019: Local AI vs Cloud AI: The Agent Identity CrisisYour desktop is becoming a life support system for AI agents. We explore the sharp trade-offs between local-first and cloud-native architectures.
-
 #2017: The Art of Squeezing AI Models onto Your GPUThose cryptic letters on Hugging Face actually map how much brain power you trade for speed.
-
 #1727: The Great Architectural Heist: LSP as AI's Universal PlumbingExplore how the Language Server Protocol is being repurposed to integrate AI directly into code editors, unifying development workflows.
-
 #1544: Why It Costs More to Run AI Than to Build ItDiscover why the AI runtime is the unsung hero of the tech stack, determining whether your AI feels like a snappy conversation or a slow crawl.
-
 #1122: Why AI Agents Are Abandoning Human LanguageWhy force AI to talk like humans? Explore how agents are ditching English for high-speed "mind-melding" and latent space communication.
-
 #1094: The CPU-First Era: Why AI is Moving Back to the ProcessorIs the GPU's reign over? Discover how modern CPUs and clever optimization are bringing powerful AI models to the hardware you already own.
-
 #857: The Cognitive Cost of CapitalizationCan local AI fix your messy typing in real-time? Explore the tech behind "transparent buffers" that turn sloppy drafts into polished prose.
-
 #8: Building Your Own WhisperEver wondered if you could build your own speech recognition tool? We dive deep into crafting custom ASR.