
#gpu-acceleration
66 episodes
#5411: Fine-Tuning at 4-Bit vs 16-Bit: What It Really Costs
QLoRA cuts fine-tuning VRAM 15x and cost up to 85% — but you pay in training time, quality, and safety alignment.
#5044: Abilene's AI Arms Race: Power, Water, and Backlash
Why a Texas town of 100,000 is hosting the biggest AI build ever—and why locals are starting to push back.
#4973: Building a Pure AI Inference Server
Why your "AI server" should look more like a database than a web app, and how to actually build one.
#4972: CPU vs GPU Inference: When to Skip the GPU
Why running AI on CPU isn't a toy — and when the GPU advantage vanishes.
#4717: Building a Home Whisper Server: The Full Spec
Daniel wants a dedicated home server for Whisper dictation. Here's the exact build — GPU, RAM, storage, and runtime — to make it work.
#4456: Inside the Podcast Pipeline: How 15 Weekly Episodes Get Made
From prompt to published episode — a full walkthrough of the automated production system running 15 shows weekly.
#4455: Borrowing a GPU Over Your Home Network
Can you use your desktop's AMD GPU from a laptop as if it were local? We explore the real options.
#4150: Computing's Hidden Price Surge: DRAM, NAND & GPUs
Why your next PC build costs 32% more than two years ago — and why no one tracks it.
#3995: Can Your Phone Upscale Photos Without the Cloud?
Local upscaling on phones is here — but which approach actually works?
#3815: Should You Rack-Mount Your Desktop PC?
Tower form factor fighting you? We explore when and how to rack-mount a desktop for better serviceability and cooling.
#3789: What Virtualization Actually Costs on 2026 Hardware
Real benchmarks show 2-6% overhead for single-VM setups. Here's what's actually happening at the CPU level.
#3755: Hermes vs OpenClaw: Mobile-to-Server AI Frameworks
Why developers are leaving OpenClaw for Hermes—and why mobile-to-server AI interaction remains unsolved.
#3218: Building Your Own Cloud in 2026
The software and hardware for a DIY private cloud have never been more feasible. Here's how to pick the right pieces.
#2941: Distrobox: Linux Containers That Feel Like Native Apps
How Distrobox merges container isolation with native desktop integration for immutable distros, GPU work, and messy builds.
#2940: Distrobox: Linux Containers for Humans, Not Servers
Run any distro's apps on any Linux host—no VM, no dual-boot, no dependency hell.
#2938: How to Prevent Linux Desktop Crashes Under Heavy Load
Stop losing work to memory exhaustion, CPU lockups, and GPU hangs on Linux workstations.
#2840: How Long Must a Password Actually Be?
The surprising math behind how long your password needs to be to survive a brute-force attack.
#2782: Are AI Data Centers Really New or Just Patched Together?
The real bottleneck isn't GPUs — it's power transformers. A look at the physics and economics of AI infrastructure.
#2779: The Hidden Stateful Side of Serverless GPU
How Modal, RunPod, and other platforms handle container builds, caching, and versioning under the hood.
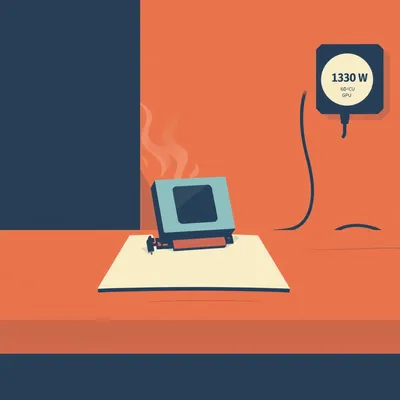
#2777: GPU Idle Waste and Serverless Green Computing
Why your dedicated GPU burns 130 watts doing nothing, and how serverless platforms cut energy waste by more than half.
#2622: How Transformers Actually Work: Attention, Tokens, and Context
How one architectural change unlocked chatbots, image generation, and protein folding — explained without the jargon.
#2517: How Unsloth Makes LLM Fine-Tuning 2x Faster
Unsloth cuts memory usage by 50-70% and speeds up training 2.2x for models like Llama 3 and Mistral.
#2495: How to Bake Personality Into an LLM in 15 Minutes
Fine-tune a model's personality with ~300 examples and a consumer GPU. SFT + DPO explained.
#2464: Batch APIs: The 50% Discount You're Probably Misusing
Batch inference APIs offer 50% off — but only for the right workloads. Here's when they actually make sense.